06: Strings and Unicode
Audience: All
Time: 90 minutes
Prerequisites: 01-05
You'll learn: String operations, Unicode, formatting, pattern matching with regex
The Big Picture
Strings are how programs work with text. Zebra treats strings as:
- Unicode-aware — Emoji, Chinese, Arabic, etc. all work correctly
- First-class — Rich library of methods
- Immutable — Can't change them after creation (create new ones instead)
- Efficient — UTF-8 encoding optimizes storage
String Basics
String Literals
# file: 06_string_basics.zbr
# teaches: string creation
# chapter: 06-Strings-and-Unicode

def main()
    # Simple string
    var greeting = "Hello"
    print(greeting)

    # With quotes inside
    var quoted = "She said \"Hello\""
    print(quoted)

    # Multi-line (triple-quoted)
    var poem = """
    Roses are red
    Violets are blue
    """
    print(poem)

    # Escape sequences
    var path = "C:\\Users\\Name\\Documents"
    var tab = "Name\tAge\tCity"
    var newline = "Line1\nLine2"
String Properties
# file: 06_string_props.zbr
# teaches: string properties and methods
# chapter: 06-Strings-and-Unicode

def main()
    var text = "Hello, World!"

    # Byte length (Unicode-aware count is below — see codePointCount)
    print(text.len)  # 13

    # Indexing gives a BYTE, not a character: text[i] is the i-th byte of the UTF-8
    # encoding, so it prints as a number. For text, take a slice (next) or iterate
    # text.chars(), which yields whole characters even when they are multi-byte.
    var first_byte = text[0]
    print(first_byte.toString())  # 72  (the byte for "H")
    print(text[0..1])             # H

    # Substring/slice
    var part: str = text[0..5]
    print(part)  # Hello

    # Case conversion
    print(text.upper())  # HELLO, WORLD!
    print(text.lower())  # hello, world!
String Interpolation
# file: 06_interpolation.zbr
# teaches: string interpolation
# chapter: 06-Strings-and-Unicode

def main()
    var name = "Alice"
    var age = 30

    # Simple interpolation
    print("Name: ${name}")  # Name: Alice

    # Expressions in interpolation
    print("Age next year: ${age + 1}")  # Age next year: 31

    # Method calls
    var lower_name = name.lower()
    print("Lowercase: ${lower_name}")  # Lowercase: alice

    # Format specifiers
    var price = 19.99
    print("Price: ${price:.2f}")  # Price: 19.99
String Methods
Searching
# file: 06_search.zbr
# teaches: searching in strings
# chapter: 06-Strings-and-Unicode

def main()
    var text = "Hello, World!"

    # Contains
    print(text.contains("World"))  # true
    print(text.contains("xyz"))  # false

    # Index — returns -1 when not found
    print(text.indexOf("World"))  # 7
    print(text.indexOf("xyz"))  # -1

    # Starts/ends with
    print(text.startsWith("Hello"))  # true
    print(text.endsWith("!"))  # true
Splitting and Joining
# file: 06_split_join.zbr
# teaches: splitting and joining strings
# chapter: 06-Strings-and-Unicode

def main()
    # Split — annotate the local with `: List(str)` to materialise the iterator
    # into an actual list (otherwise it stays as a forward iterator only).
    var csv = "apple,banana,cherry"
    var fruits: List(str) = csv.split(",")
    for fruit in fruits
        var f: str = fruit
        print(f)

    # Join
    var items = List(str)()
    items.add("one")
    items.add("two")
    items.add("three")
    var result = ", ".join(items)
    print(result)  # one, two, three
Trimming and Padding
# file: 06_trim_pad.zbr
# teaches: trimming and padding
# chapter: 06-Strings-and-Unicode

def main()
    var padded = "  hello  "

    # Trim whitespace
    print("|${padded.trim()}|")  # |hello|
    print("|${padded.trimLeft()}|")  # |hello  |
    print("|${padded.trimRight()}|")  # |  hello|

    # Padding
    var short = "hi"
    print(short.padLeft(10, "*"))  # ********hi
    print(short.padRight(10, "-"))  # hi--------
    print(short.center(10, "*"))  # ****hi****
Replacing
# file: 06_replace.zbr
# teaches: string replacement
# chapter: 06-Strings-and-Unicode

def main()
    var text = "cat and dog and bird"

    # Replace (first occurrence, or all)
    var once = text.replace("and", "or")      # Replaces once
    print(once)

    var all = text.replaceAll("and", "or")    # Replaces all
    print(all)

    # Case conversion
    var lower = "Hello World".lower()
    print(lower)  # hello world
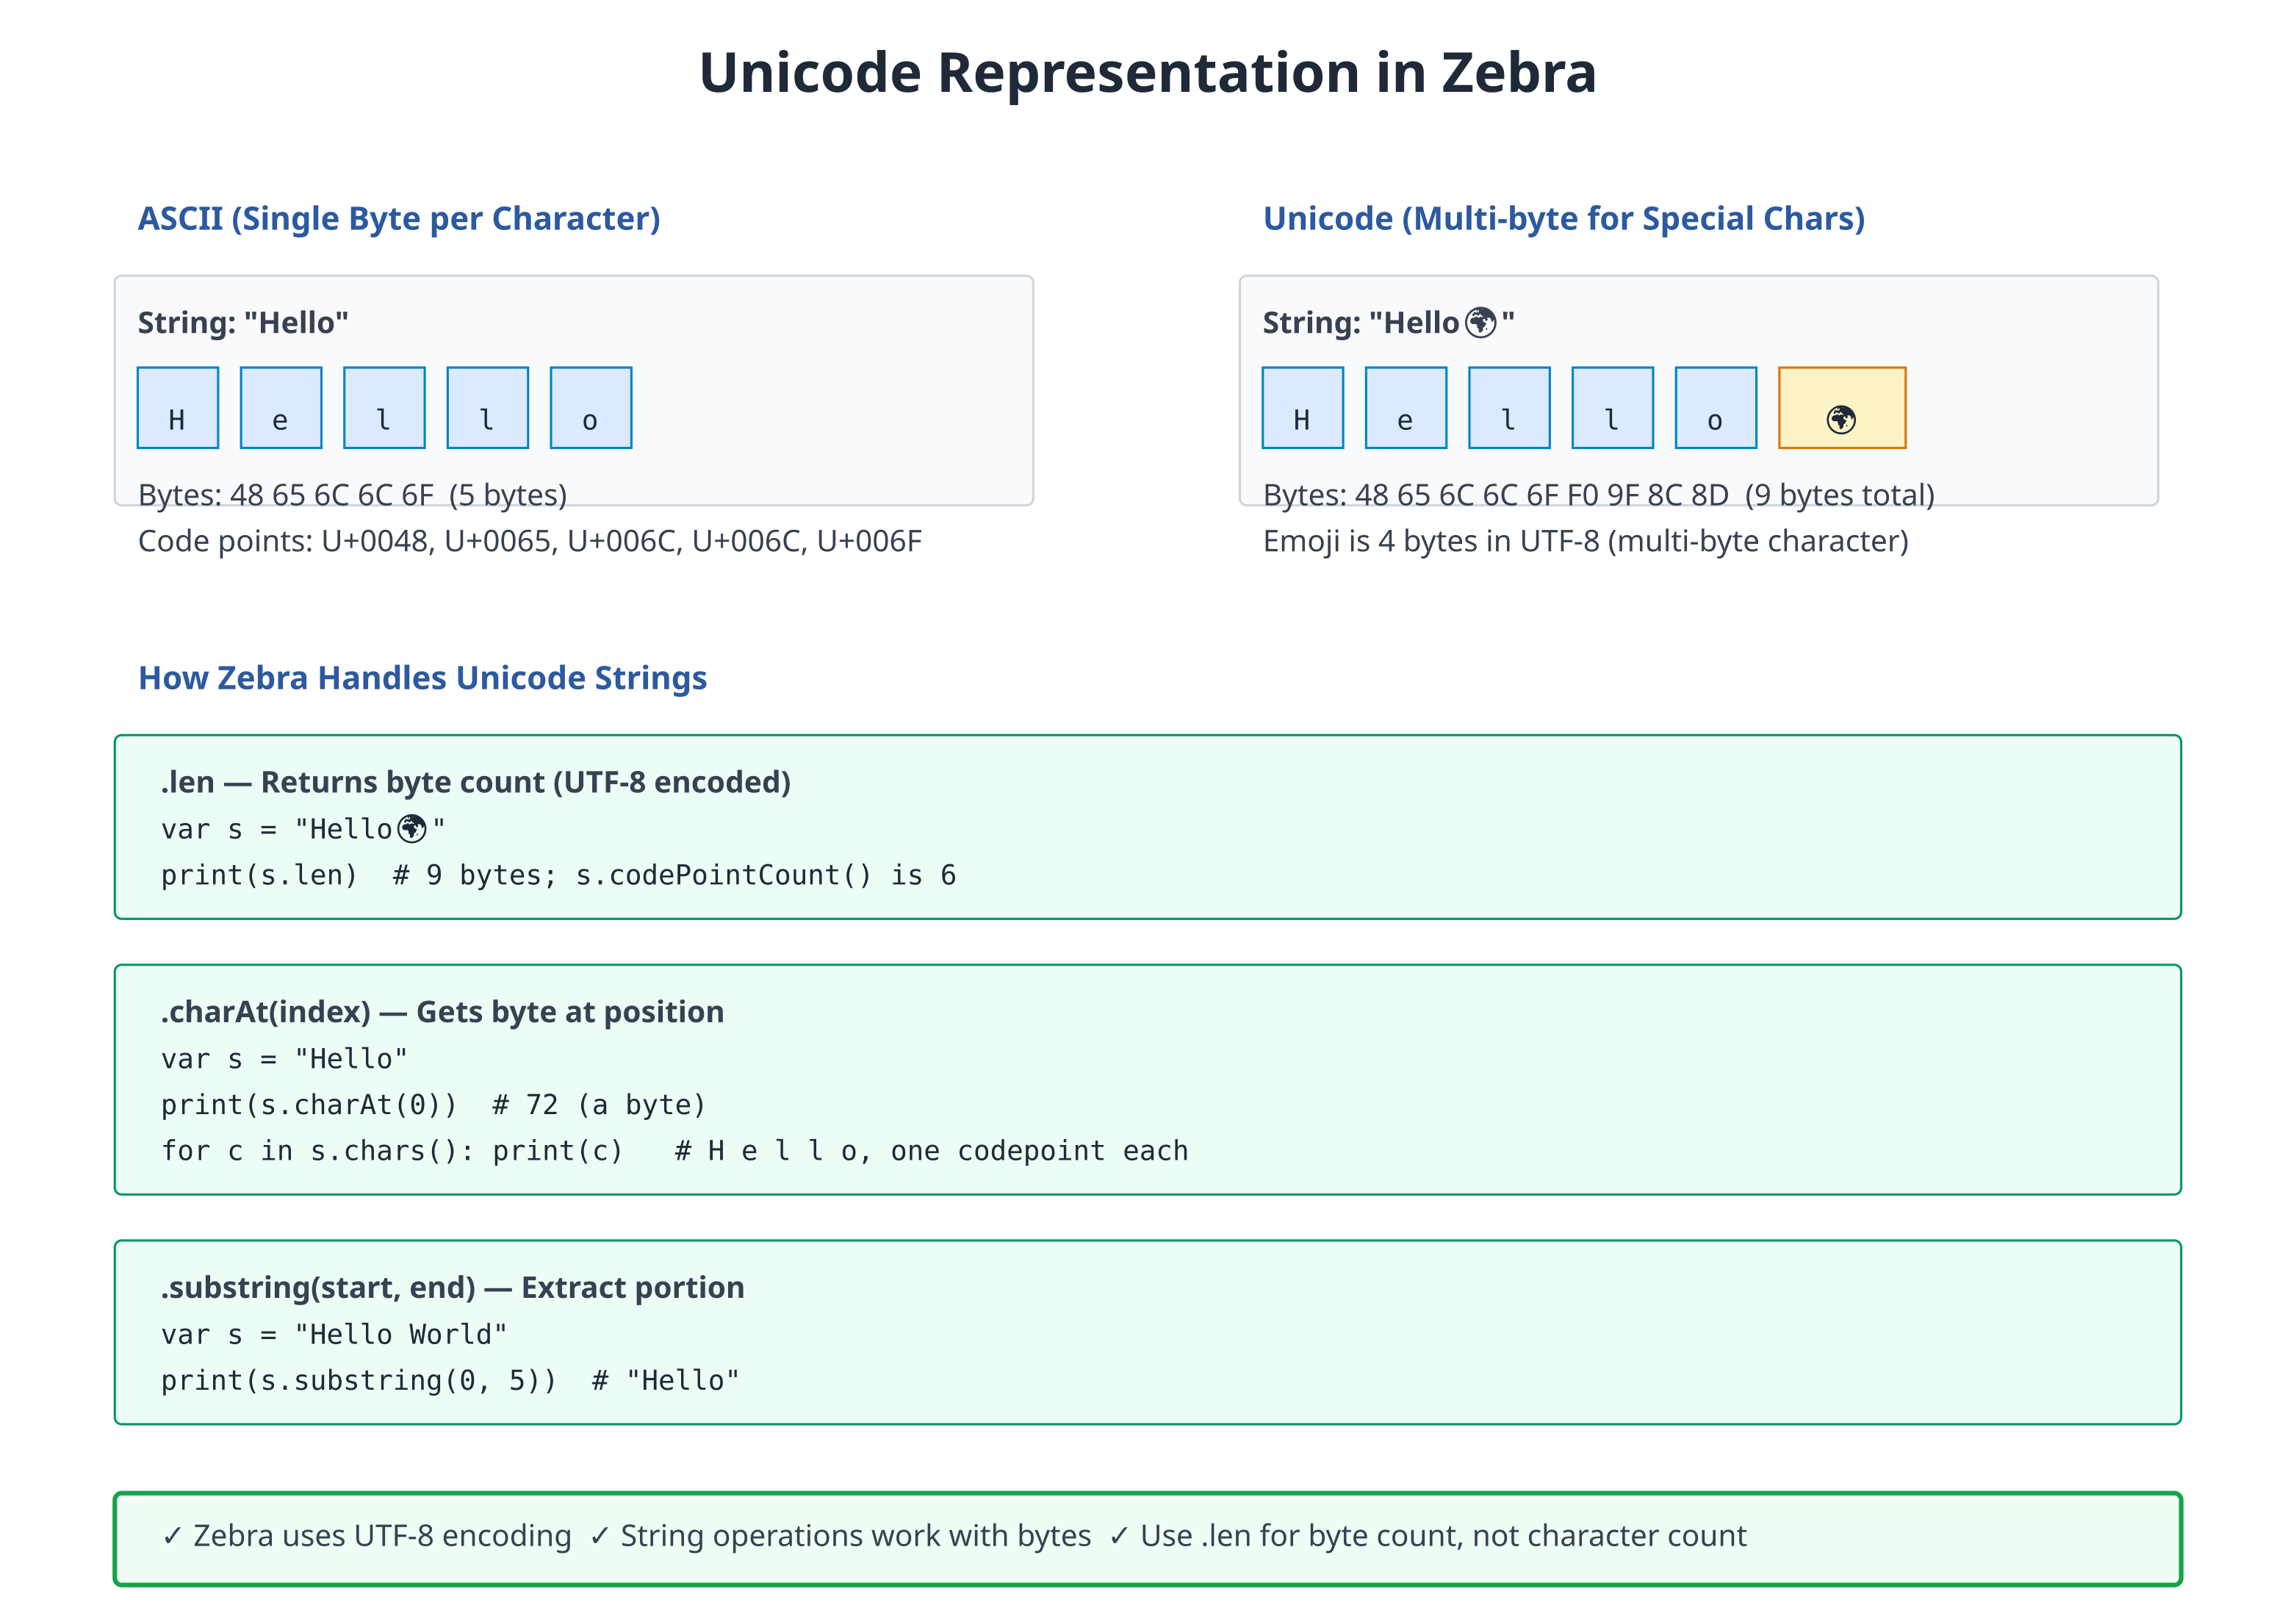
Unicode and Internationalization
Unicode Basics
# file: 06_unicode.zbr
# teaches: unicode support
# chapter: 06-Strings-and-Unicode

def main()
    # Emoji
    var emoji = "Hello 👋 🌍 🎉"
    print(emoji)
    print(emoji.len)  # Byte length
    print(emoji.codePointCount())  # Character count

    # Chinese
    var chinese = "你好世界"             # Hello World in Chinese
    print(chinese)

    # Arabic (right-to-left)
    var arabic = "مرحبا بالعالم"         # Hello World
    print(arabic)

    # Mixed scripts
    var mixed = "Hello 世界 مرحبا"
    print(mixed)
Character Iteration
# file: 06_char_iter.zbr
# teaches: iterating over characters
# chapter: 06-Strings-and-Unicode

def main()
    var text = "Hello"

    # Iterate characters (yields `char`; .toString() lifts back to str for printing)
    for c in text.chars()
        print(c.toString())

    # Byte iteration — yields each byte as a u8
    var data = "AB"
    for byte in data.bytes()
        print(byte)  # 65, 66 (ASCII values)
.chars()and.bytes()are different lenses on the same string..chars()walks Unicode codepoints (so"👋"yields one element);.bytes()walks the raw UTF-8 bytes (so"👋"yields four). Use whichever matches what you're counting.
Regular Expressions (Intro)
Regular expressions let you search and validate text patterns.
Basic Patterns
# file: 06_regex_intro.zbr
# teaches: regular expressions introduction
# chapter: 06-Strings-and-Unicode

def main()
    # Simple pattern
    var email = "alice@example.com"
    var pattern = Regex.compile("[a-z]+@[a-z]+\\.[a-z]+")

    print(pattern.match(email))  # true

    # Find matches
    var text = "I have 2 apples and 3 oranges"
    var digit_pattern = Regex.compile("\\d+")
    if digit_pattern.find(text) as found
        print(found)  # 2

    # Replace
    var clean = digit_pattern.replace(text, "X")
    print(clean)  # I have X apples and X oranges
Real World: Text Processing
# file: 06_text_processing.zbr
# teaches: practical text operations
# chapter: 06-Strings-and-Unicode

def parse_csv_line(line: str): List(str)
    var out: List(str) = line.split(",")
    return out

def normalize_whitespace(text: str): str
    var lines = List(str)()
    for line in text.split("\n")
        var trimmed = line.trim()
        if trimmed.len > 0
            lines.add(trimmed)
    return "\n".join(lines)

def extract_numbers(text: str): List(str)
    var results = List(str)()
    var pattern = Regex.compile("\\d+")
    for match in pattern.findAll(text)
        results.add(match)
    return results

def main()
    # Parse CSV
    var csv_line = "Alice,30,alice@example.com"
    var fields = parse_csv_line(csv_line)
    var name: str = fields.at(0)
    var age:  str = fields.at(1)
    print("Name: ${name}")
    print("Age: ${age}")

    # Extract numbers
    var text = "I was born in 1990 and moved in 2005"
    var years = extract_numbers(text)
    for year in years
        var y: str = year
        print(y)
Common Patterns
Email Validation
def is_valid_email(email: str): bool
    if not email.contains("@")
        return false
    var parts: List(str) = email.split("@")
    if parts.count() != 2
        return false
    var domain: str = parts.at(1)
    if not domain.contains(".")
        return false
    return true
URL Parsing
def parse_url(url: str): HashMap(str, str)
    var result = HashMap(str, str)()
    var parts: List(str) = url.split("://")
    if parts.count() == 2
        var proto: str = parts.at(0)
        result.put("protocol", proto)
    return result
String Templating
def template(text: str, values: HashMap(str, str)): str
    var result = text
    for key, value in values
        var placeholder = "${${key}}"
        result = result.replace(placeholder, value)
    return result
Common Mistakes
❌ Mistake: Forgetting that strings are immutable
var text = "hello"
text[0] = 'H'  # ❌ Can't modify
✅ Better:
var text = "hello"
var capitalized = "H".concat(text[1..])
❌ Mistake: Ignoring Unicode length
var emoji = "👋"
print(emoji.len)  # ❌ Returns 4 (bytes), not 1
✅ Better:
var emoji = "👋"
print(emoji.codePointCount())  # ✅ Returns 1 (characters)
❌ Mistake: Inefficient concatenation in loops
var result = ""
for i in 1.to(1000)
    result = result + "${i},"  # ❌ O(n²) complexity
✅ Better:
var sb = StringBuilder()
for i in 1.to(1000)
    sb.append("${i},")
var result = sb.build()  # ✅ O(n) complexity
Exercises
Exercise 1: String Reversal
Write a function that reverses a string:
Solution
def reverse_str(text: str): str
    var chars = List(str)()
    for c in text.chars()
        chars.add(c.toString())

    var result = ""
    var i = chars.count() - 1
    while i >= 0
        result = result.concat(chars.at(i))
        i = i - 1
    return result

def main()
    var reversed = reverse_str("hello")
    print(reversed)  # olleh
Zebra also has a built-in
text.reverse()for the common case; the loop above is just to show character iteration.
Exercise 2: Email Validator
Write a simple email validator:
Solution
def is_valid_email(email: str): bool
    if email.len < 5
        return false
    if not email.contains("@")
        return false
    if not email.contains(".")
        return false
    var parts: List(str) = email.split("@")
    if parts.count() != 2
        return false
    var domain: str = parts.at(1)
    if domain.len < 3
        return false
    return true

def main()
    var emails = List(str)()
    emails.add("alice@example.com")
    emails.add("invalid")
    emails.add("bob@domain.co")

    for email in emails
        var e: str = email
        if is_valid_email(e)
            print("Valid: ${e}")
        else
            print("Invalid: ${e}")
Exercise 3: CSV Parsing
Parse a CSV line and extract fields:
Solution
def parse_csv(line: str): List(str)
    var out: List(str) = line.split(",")
    return out

def parse_with_trim(line: str): List(str)
    var trimmed = List(str)()
    for field in line.split(",")
        trimmed.add(field.trim())
    return trimmed

def main()
    var csv = "Alice, 30, NYC"
    var fields = parse_with_trim(csv)
    for field in fields
        var f: str = field
        print("|${f}|")
Next Steps
- → 07-Classes — Object-oriented programming
- → 18-Regular-Expressions — Deep dive into regex
- 🏋 Project-1-CLI-Tool — Text processing practical application
Key Takeaways
- Strings are immutable — Create new ones instead of modifying
- Interpolation is readable — Use
"${var}"over concatenation - Methods are rich —
.split(),.replace(),.trim(), etc. - Unicode works seamlessly — emoji, Chinese, Arabic, etc.
- Regex enables pattern matching — For validation and extraction
- StringBuilder is efficient — Use for loop-based concatenation
Next: Head to Part 2 for object-oriented programming with 07-Classes.